AI & Hackathons•July 15, 2026•4 min read
What I Learned Building VetoAI in 24 Hours at India AI Summit
High-speed hackathon prototyping, low-latency LLM inference with Groq, and autonomous debate judging.
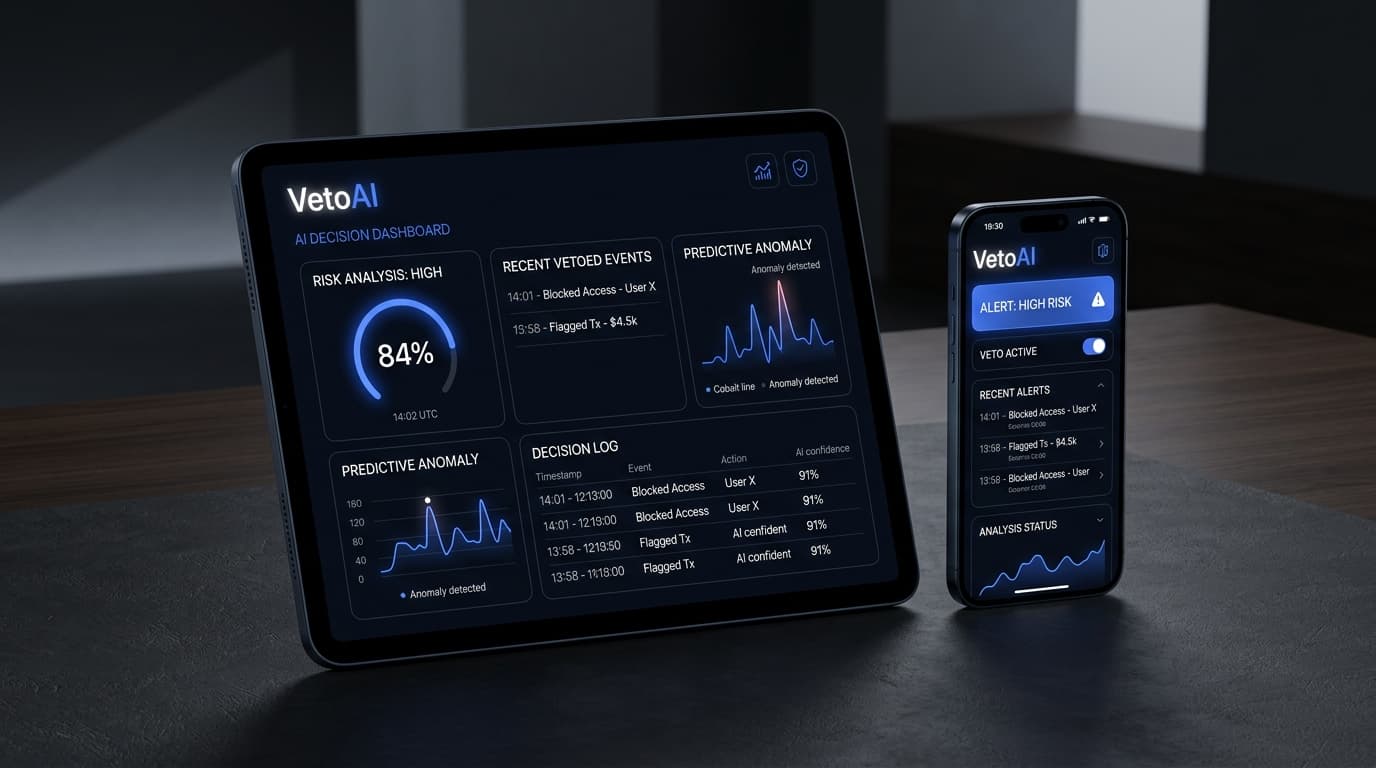
### The 24-Hour Sprint At the India AI Impact Festival, our team wanted to tackle a nuanced problem: subjective bias in parliamentary debate adjudication. Human judges often favor charismatic delivery over substantive logical reasoning.
The Technical Stack - **Inference Engine**: Groq Llama 3 70B for sub-300ms token streaming - **Framework**: Next.js 14 with Server-Sent Events (SSE) - **Scoring Pipeline**: Dual-pass evaluation analyzing premise-conclusion validity, fallacy detection, and rebuttal weight
const debateScorer = async (transcript: string) => {
  const analysis = await groq.chat.completions.create({
    model: "llama-3.3-70b-versatile",
    messages: [
      { role: "system", content: "Analyze parliamentary debate transcript for logical fallacies and premise cohesion." },
      { role: "user", content: transcript }
    ],
    response_format: { type: "json_object" }
  });
  return JSON.parse(analysis.choices[0].message.content);
};
Key Takeaway High-pressure hackathons reveal the importance of modular component design. Because we had a battle-tested design token system ready, we spent 85% of our time perfecting the AI logic rather than fighting CSS.
Documented By
Aryan Maurya
Student Developer & Creative Technologist · Delhi, India
#AI#Hackathon#Groq#Llama 3